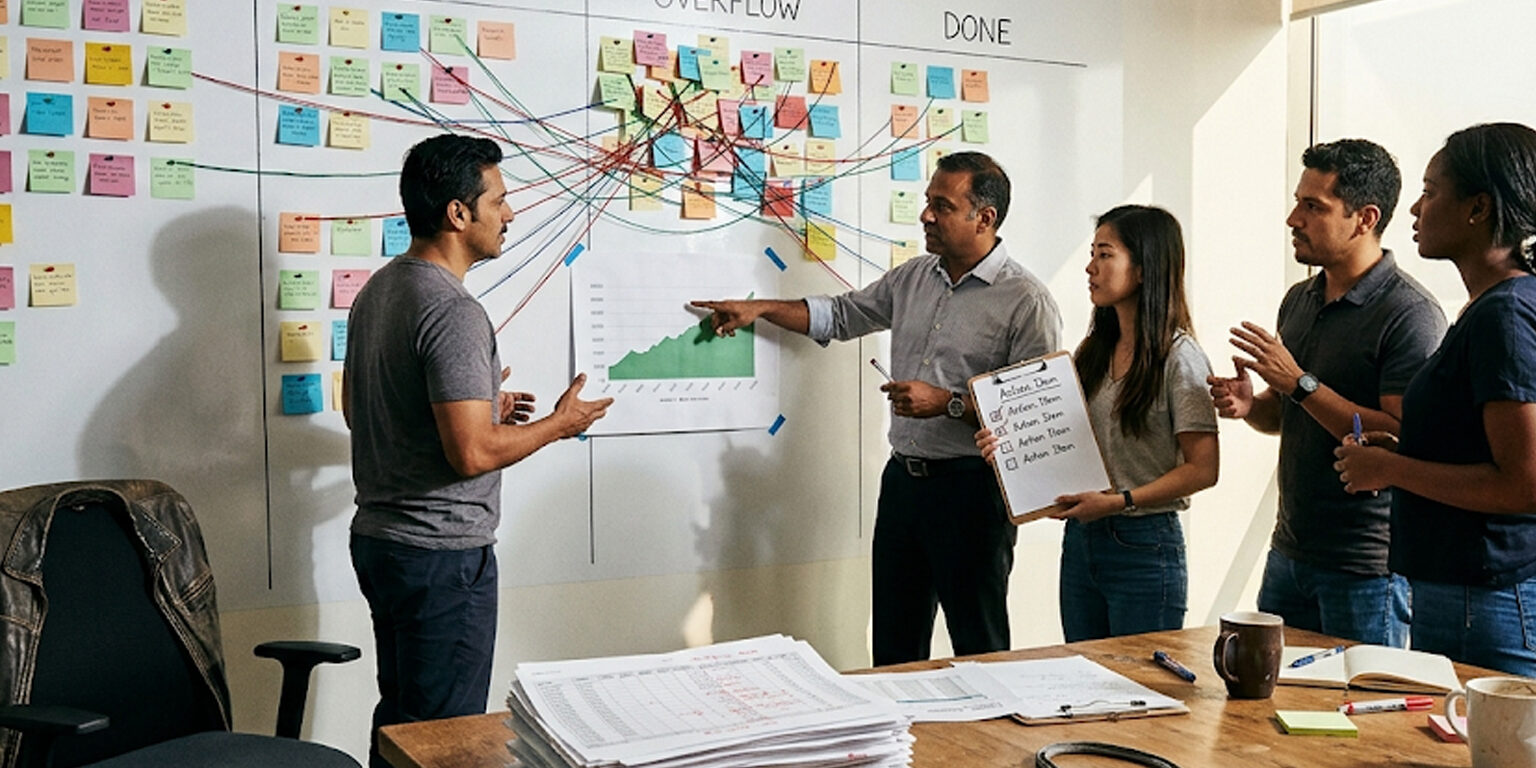
Scaling isn’t an abstract goal; it happens when routine work starts to strain capacity.
Leaders who watch for specific operational tipping points make cleaner decisions about hiring, tooling, and process investment.
This article highlights practical signals — not theory — that suggest it’s time to invest.
Spotting them early keeps small challenges from becoming expensive crises.
Common operational strains that precede scaling
The first sign is recurrent firefighting: the same problems reappear week after week despite temporary fixes.
Another is a backlog that grows faster than the team can clear, creating longer lead times and missed commitments.
When single individuals hold tribal knowledge and work piles up when they’re unavailable, capacity has a single point of failure.
Customer complaints, slipping delivery dates, and rising rework are all concrete indicators that processes no longer absorb demand.
When tools can’t keep up — spreadsheets ballooning, ticket queues unmanaged — the gap becomes obvious.
- Repeated workarounds that never get formalized.
- Long approval cycles that freeze progress.
- Overloaded core people who are constant bottlenecks.
These challenges are operational, not just cultural; they respond to clarified roles, simpler handoffs, and modest automation.
You don’t need perfect systems, but you do need predictable pathways to handle recurring work.
Simple metrics that reveal hidden bottlenecks
Quantitative signals often beat anecdotes: track cycle time, the size of your backlog, and the frequency of rollbacks or rework.
A steady rise in cycle time without a change in work scope means throughput is degrading.
Monitor handoff delays between teams; a day of waiting multiplies into weeks when work chains are long.
Also measure how often tasks return for revision — that points to unclear requirements or weak quality gates.
Customer-facing metrics like response time and churn can corroborate internal bottlenecks.
Choose two metrics you can measure this week and review them at the same meeting each cycle.
Simple, consistent measures create the evidence leaders need to justify operational investment.
Practical steps to take before you expand resources
Start with small experiments: designate a focused pilot to reduce handoff points or automate a repeatable task.
Document ownership for critical workflows so problems are visible and accountabilities are clear.
Before hiring, map what extra capacity should accomplish in measurable terms — fewer escalations, faster cycle time, higher throughput.
Pilot tools and changes with limited scope; evaluate their impact on the metrics you already track.
Align any new hires to specific process gaps rather than vague workload forecasts.
- Run a two-week pilot on a single workflow.
- Document outcome metrics before and after the change.
If pilots improve your chosen metrics and reduce manual coordination, scale the change incrementally.
This reduces risk and makes the case for investment visible to stakeholders.
Conclusion
Operational tipping points are measurable and manageable when you focus on recurring strain and simple metrics.
Act with small experiments, clear ownership, and two dependable measures before committing significant resources.
Doing so turns reactive scaling into a controlled, high-confidence decision.