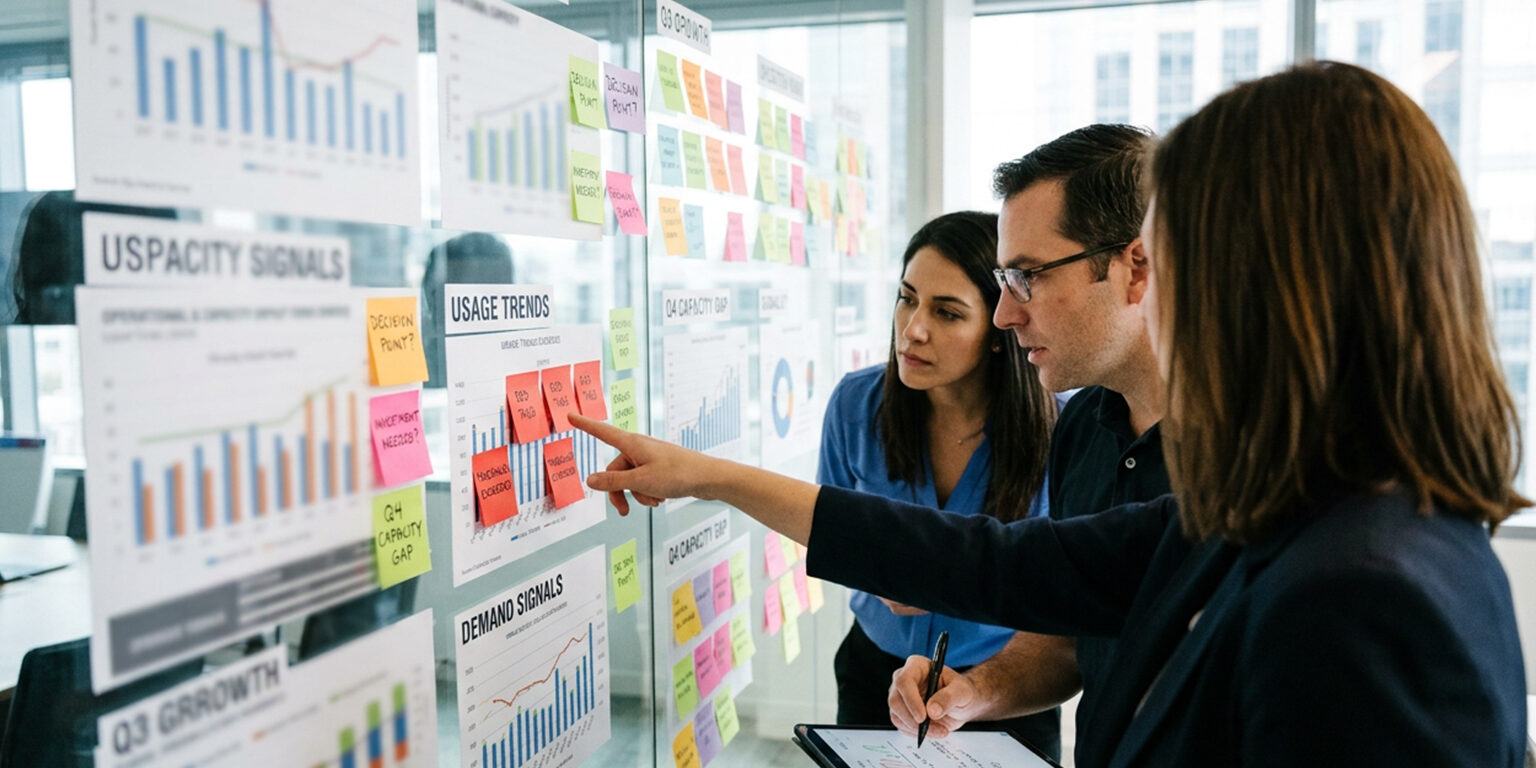
Leaders need clear, observable signals to decide when to invest in capacity. Waiting for obvious crises wastes momentum, while premature hires and systems spend waste resources. Practical operational signals create a defensible case for timing investments and reduce emotional decision-making. This piece outlines measurable indicators that show when scaling operations will likely pay off.
Throughput and Cycle Time
Track how quickly work moves from start to finish and whether throughput is stable or declining. Increasing cycle times or uneven throughput often indicate bottlenecks in tools, processes, or handoffs. These changes are measurable and tend to precede customer-visible slowdowns, making them reliable early warnings. Monitoring trends over weeks rather than days reduces noise and highlights persistent constraints.
When sustained degradation shows in these metrics, consider targeted investments. Small process automation or focused staffing at the bottleneck often yields disproportionate gains.
Team Load and Decision Friction
Measure how often teams defer decisions or route approvals upward to leadership; that pattern signals unclear decision rights or excessive cognitive load. High context-switching, frequent overtime, and late-stage rework also reflect capacity stress. Surveys and simple workload logs can quantify cognitive load and repeated stop-starts in work. Those indicators are particularly useful because they connect team health to predictable delivery outcomes.
Addressing decision friction can be cheaper than adding headcount. Clarify roles, standardize recurring decisions, and free leaders from tactical approvals before expanding teams.
Quality Signals and Customer Impact
Errors, rework rates, and customer complaints tend to rise when capacity is stretched, translating internal friction into external cost. These metrics tie operational strain to revenue and reputation, making them persuasive for investment conversations. Consider a short list of customer-impact indicators to watch and report regularly to stakeholders.
- Repeat support tickets per customer
- Time to resolve critical incidents
- Percentage of releases with hotfixes
If quality metrics worsen alongside throughput or load indicators, prioritize investments that reduce rework—improving predictability often removes the need for immediate scale hires.
Conclusion
Combine throughput, team load, and quality signals to form a balanced readiness score. Use trend-based thresholds rather than one-off spikes to decide on investments. This approach makes scaling timely, evidence-driven, and less risky.